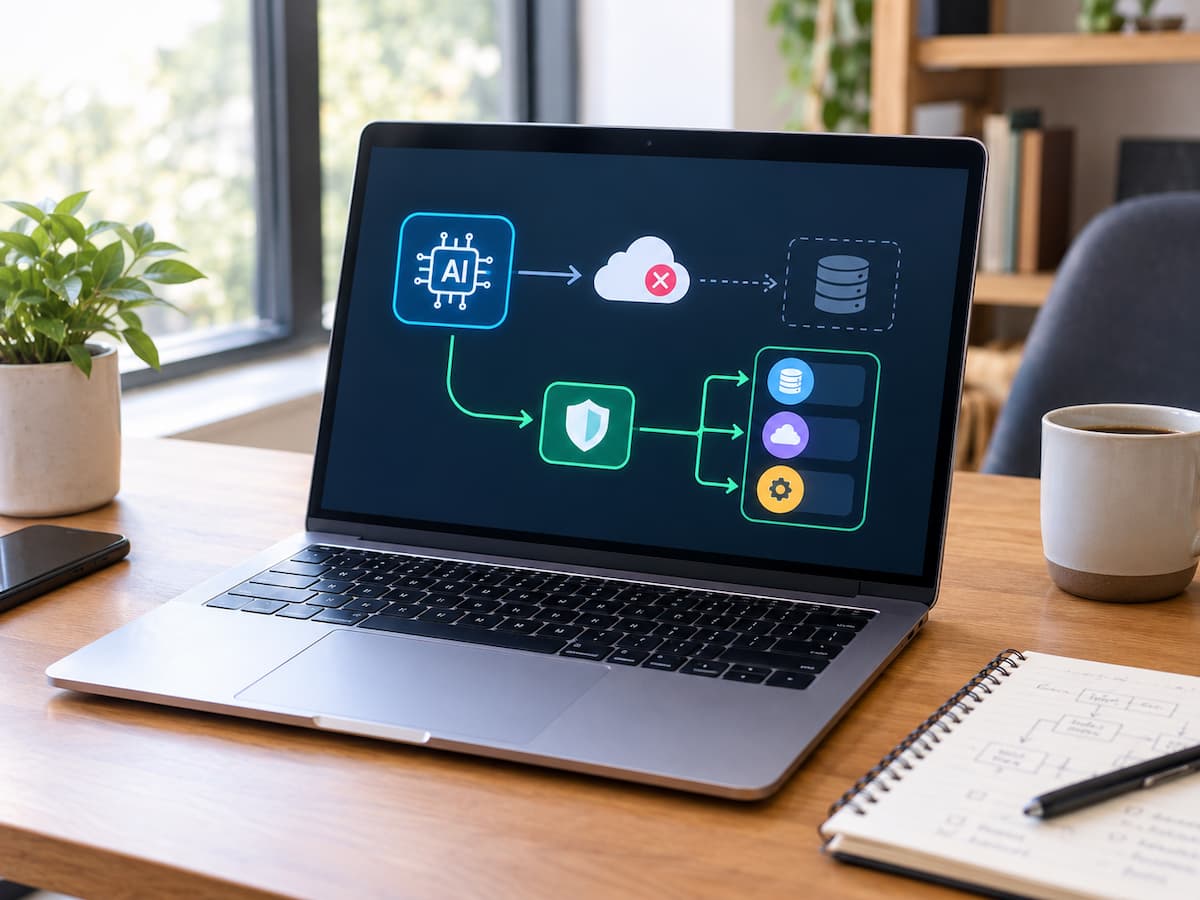
An AI automation can work perfectly for weeks and still fail at the worst possible moment. A document-processing workflow may stop because an AI service is unavailable. A support system may receive an error when its model reaches a usage limit. An automation that normally classifies incoming messages may suddenly return incomplete results or take too long to respond.
The problem is not simply that the AI service stopped working. The bigger problem is what the automation does next. Without a fallback, one failed step can stop an entire workflow. With a sensible fallback, the same failure may cause a smaller delay, switch to another method, or send the task to a person for review. A sensible fallback does not try to hide every failure. It gives the automation a controlled way to respond when its normal path is unavailable.
Start By Defining What “Failure” Means
A fallback is only useful when the automation can recognise when it should be used. Treating every unusual result as a service outage can create new problems. There are several different types of failure worth separating.
- The service is unreachable. The AI provider may be temporarily unavailable, a network connection may fail, or a request may not reach the service.
- The request is rejected. An account may reach a usage limit, a request may exceed a service limit, or authentication may fail.
- The service responds, but the result is unusable. This is more subtle. A request can technically succeed while producing an empty, incomplete, malformed, or otherwise unsuitable result.
- The response takes too long. An automation may technically receive an answer eventually, but waiting indefinitely can hold up every later step.
- The input itself is unsuitable. A workflow designed for text may receive an unexpected file, an unusually large document, or information in a format the process was not designed to handle.
These conditions do not always need the same response. A temporary network problem might justify a retry, while a suspicious or incomplete AI result may need human review.
Decide What Must Continue and What Can Stop
Not every automation needs a complicated backup system.
The first useful question is: What happens if this AI step produces nothing?
Imagine an automation that reads incoming customer messages and places each one into a category. If classification fails, the message might simply remain in a general queue for someone to review. That is very different from an automation that uses AI to prepare information for a later financial or operational decision. The consequences of failure determine the strength of the fallback you need.
A low-risk workflow might safely use:
- One automatic retry.
- A simpler non-AI rule.
- A notification that the task needs attention.
A more important workflow may need:
- Limited retries with controlled delays.
- A second processing method.
- Validation of the replacement result.
- A human review step.
- A record of what failed and what action was taken.
The goal is to make only necessary automations continue. Sometimes stopping is the safest fallback.
Use Retries for Temporary Problems, Not Every Problem
A retry is often the simplest fallback, but it should not be the only one. Suppose an AI request fails because of a brief connection problem. Trying the same request again after a short delay may solve the problem without requiring another system.
However, repeating a request immediately and indefinitely can worsen the situation. If the service is already overloaded, sending more requests can add unnecessary pressure. It can also cause duplicate work or unexpected costs when requests are not safely repeatable.
A retry strategy should therefore answer three questions:
- How many times should the request be retried?
- How long should the automation wait between attempts?
- Which types of errors should trigger a retry?
A temporary service or network error may be reasonable to retry. A permanently invalid request is usually valid. If the input exceeds a known limit, sending the same oversized request again will not resolve it. For workflows that can create records, send messages, or perform transactions, also consider whether repeating the operation could create a duplicate. A retry should be designed with the possibility that the first attempt may have succeeded even if the automation did not receive a clear confirmation.
Give the Workflow a Simpler Second Path
A fallback does not always require another AI model. Sometimes the most dependable backup is an ordinary rule. Consider an automation that uses AI to identify whether an incoming document is an invoice, receipt, or general file. If the AI service becomes unavailable, the workflow could examine the filename, file type, sender, or other structured information and place uncertain files into a review folder.
That will not reproduce the full intelligence of the normal process. It does not need to. The purpose of the fallback is to preserve useful progress without pretending that the simpler method is equally capable.
A second path might use:
- Fixed rules
- Existing metadata
- Regular expressions
- Required fields
- Previously validated categories
- A manual review queue
- A simpler processing method
This approach is especially useful when some decisions are certain while others genuinely require AI.
Keep Human Review as a Real Option
A common mistake is designing an automation with only two outcomes: success or failure. There is often a valuable third outcome: it needs review.
For example, suppose an AI system extracts information from a form. The normal process might accept the extracted fields when they pass basic validation. If the AI service fails completely, the form can be placed in a review queue rather than discarded. Human review is particularly useful when the cost of an incorrect automated decision is greater than the cost of a delay. The workflow should make the review task clear. A person should be able to see what the automation received, what step failed, and what information is still needed.
Sending a vague notification such as “AI automation failed” puts too much work on the person receiving it. A useful alert might instead identify the affected item, the failed stage, the time of failure, and the action already taken.
Separate the AI Step From the Rest of the Workflow
Fallbacks become easier to design when the AI service is treated as one component rather than as the entire automation.
Imagine this sequence:
Receive file → store file → send content to AI → validate result → update system
If the AI step is tightly connected to every other step, its failure can make the whole process difficult to recover. A more resilient design treats each stage separately. The original file can remain safely stored even if analysis fails. The workflow can then retry the AI step later without asking the user to submit the file again.
This separation also helps prevent data loss. The system should not depend on an AI response being available before preserving important input. In practical terms, consider where the workflow can safely pause. A suitable pause point lets the process resume later without repeating any work.
Validate the Fallback Result Before Using It
Switching to a backup path does not automatically make the result safe. Suppose the main AI service extracts three fields from a document, while the fallback method can extract only one. If the next automation step assumes that all three fields exist, the fallback may cause a different type of failure. Validation should therefore happen after important processing steps, including fallback processing.
Useful checks can include:
- Is the expected field present?
- Is the value in the correct format?
- Is a required identifier missing?
- Is the result within an acceptable range?
- Did the system receive an empty response?
- Does the output contain unexpected content?
- Is the confidence or certainty information, when available, sufficient for the next step?
Validation does not prove that an AI result is correct. It simply catches obvious conditions that should prevent an unsafe or unusable result from moving forward. For higher-risk tasks, validation may need to be performed by a person rather than another automated step.
Be Careful When Using a Second AI Service
Using another AI provider as a backup can improve availability, but it introduces additional decisions. Different services may handle the same input differently. They may use different interfaces, output formats, limits, data-retention policies, or security controls. A prompt that works with one service may not produce the same structure elsewhere. There is also a privacy question.
If the normal service is allowed to process a particular type of information, that does not automatically mean a backup service should receive the same information. Sensitive business documents, personal information, credentials, confidential communications, or other restricted data may require additional controls. Before routing information to another provider, verify the applicable terms, security settings, data handling practices, and organisational requirements. A fallback should never become an excuse to send data somewhere that the original workflow was not permitted to use.
Design Around Timeouts and Delays
An automation can fail without returning an obvious error. If a workflow waits indefinitely for an AI response, later steps may never execute. Eventually, the result may look like a complete system failure even though the underlying problem is simply that one operation never finished.
Set a reasonable timeout for operations where the platform supports it. Once the timeout is reached, the workflow can decide whether to retry, use a backup method, or place the task into a waiting state. The correct timeout depends on the task. A short text classification may have a different acceptable delay from processing a large document. The important point is to define what “too long” means before an outage occurs.
Preserve Enough Information to Recover
A fallback is much more useful when the automation leaves behind a clear record.
At minimum, consider recording:
- When the task started
- Which processing step failed
- The type of failure
- Whether a retry was attempted
- Which fallback path was used
- Whether the fallback succeeded
- Whether human review is required
- The final status
This information helps distinguish between a one-time problem and a recurring weakness in the workflow. It also makes recovery easier. If hundreds of tasks accumulate during an outage, you need to know which ones were completed, which ones were retried, and which ones still require attention. Avoid storing sensitive information in logs unless there is a clear reason and appropriate protection. A useful operational record does not need to contain the full contents of every document or message.
Avoid Creating a Chain of Fragile Fallbacks
It can be tempting to build a long chain:
AI service A → AI service B → AI service C → another API → manual process
More fallback options do not automatically create a stronger system. Each additional dependency can introduce its failure, cost, security concern, and maintenance requirement. If the workflow becomes difficult to understand, troubleshooting can become harder than the original problem.
A simpler design is often easier to maintain:
Primary method → limited retry → practical fallback → human review
The exact structure will vary, but every branch should have a clear purpose. If a fallback is rarely used, it should still be tested occasionally. An emergency path that has never been exercised may fail when it is finally needed.
Test Failure Before You Need the Fallback
The best time to discover a broken fallback is during a controlled test, not during a real outage. Test different conditions separately. Disconnect the service if your environment allows safe testing. Use an invalid response. Simulate a timeout. Provide an incomplete input. Test what happens when the backup method also fails. Then follow the workflow all the way to its final state.
A useful test asks more than “Did the fallback run?”
It should also ask:
- Did the original data remain safe?
- Did the workflow create a duplicate?
- Did the next step receive a valid result?
- Was someone notified when human attention was required?
- Can the task be resumed without starting from the beginning?
These questions reveal weaknesses that a simple success test will miss.
A Practical Example of a Resilient AI Workflow
Consider a small business that automatically summarises incoming support messages and stores the summaries in a task system.
The normal path could be:
New message → AI summary → output validation → task creation
A sensible fallback design might work like this:
- If the AI request fails temporarily, the system retries a limited number of times.
- If the request still fails, the original message is preserved and the task is placed into a “summary pending” queue.
- If a simpler rule-based process can identify basic information, it may add that information to the task without generating a full summary.
- If neither method can produce a usable result, the task is marked for human review.
The important part is that the customer message is not lost merely because the AI service is unavailable. Once the main service returns, pending items can be processed again. The workflow should also verify whether a task was already created before attempting to create another one. This example illustrates an important principle: the fallback protects the workflow’s state, not just its AI output.
Know When Stopping Is Better Than Falling Back
There are situations where continuing automatically is the wrong choice. If a fallback cannot provide information required for a safe decision, the workflow should stop that stage and request human intervention.
For example, an automation should not invent a missing value simply because the main AI service is unavailable. It should not silently replace uncertain information with a guess. A controlled failure can be much safer than an incorrect success.
The fallback decision should therefore be based on the consequences of being wrong. If an incorrect output could cause significant financial, legal, security, privacy, or operational harm, use stronger validation and consider requiring human approval.
Build Fallbacks Around the Real Weak Point
A useful fallback is not necessarily the most technically impressive one. It is the one that addresses the actual consequence of failure.
- For some workflows, the biggest risk is losing incoming data. The fallback should preserve the input.
- For others, the problem is delay. A queue may be more useful than another AI provider.
- For tasks involving uncertain decisions, human review may matter more than automatic recovery.
Before adding another service or writing complicated recovery logic, identify what must be protected: the data, the workflow state, the deadline, the decision, or the user experience. Once that is clear, the fallback becomes much easier to design.
Conclusion
A dependable AI automation should have a defined response for the moment its preferred service is unavailable, delayed, or unreliable. That response does not have to reproduce the full capability of the main system. It may retry briefly, use a simpler rule, preserve the task for later processing, or send the work to a person. The strongest designs also validate fallback results, protect sensitive information, prevent duplicate actions, record useful failure details, and test recovery paths before they are needed.
Most importantly, decide in advance when the automation should continue and when it should stop. A system that knows how to fail safely is often more useful than one that is designed only for successful runs.
FAQs
1. What Is A Fallback In An AI Automation?
A fallback is an alternative action used when the normal AI-based step cannot complete its job. It might be a retry, a rule-based process, another approved service, a queue for later processing, or human review.
2. Should Every AI Automation Have a Backup AI Service?
No. A second AI service is only one possible fallback. For many workflows, preserving the input and placing the task into a review or retry queue is simpler and safer than sending information to another provider.
3. How Many Times Should An AI Request Be Retried?
There is no universal number. The retry policy should depend on the type of error, the importance of the task, the service limits, and the risk of duplicate processing. Temporary failures may justify limited retries, while invalid requests usually need correction rather than repetition.
4. What Should Happen If Both The Main And Backup Methods Fail?
The workflow should move to a clearly defined final state. Depending on the task, this could mean storing the work for later, alerting a person, or stopping the process. Important input should not be discarded simply because automated processing failed.
5. Is Human Review A Good Fallback For AI Workflows?
Yes, particularly when an incorrect result could cause significant harm or when the available automated alternatives cannot provide enough confidence. Human review works best when the reviewer receives the original input and clear information about what the automation could not complete.
6. How Can A Fallback Create Security Or Privacy Problems?
A fallback can introduce a new service, data path, or storage location. If sensitive information is sent to a different provider or logged unnecessarily, the workflow may create risks that did not exist in the original design. Each fallback should therefore follow the same data-handling and access requirements as the primary process.
7. How Often Should AI Fallbacks Be Tested?
A fallback should be tested before relying on it in production and checked again when important parts of the workflow change. Testing should cover more than whether the backup activates; it should also confirm that data is preserved, duplicate actions are avoided, notifications work, and failed tasks can be recovered.